Jev is not a chatbot. That is precisely what makes the model interesting
TypeSafe AI is not building another writing tool, but rather a fast decision function for structured software processes. Published on 21 September 2026 • AI translated
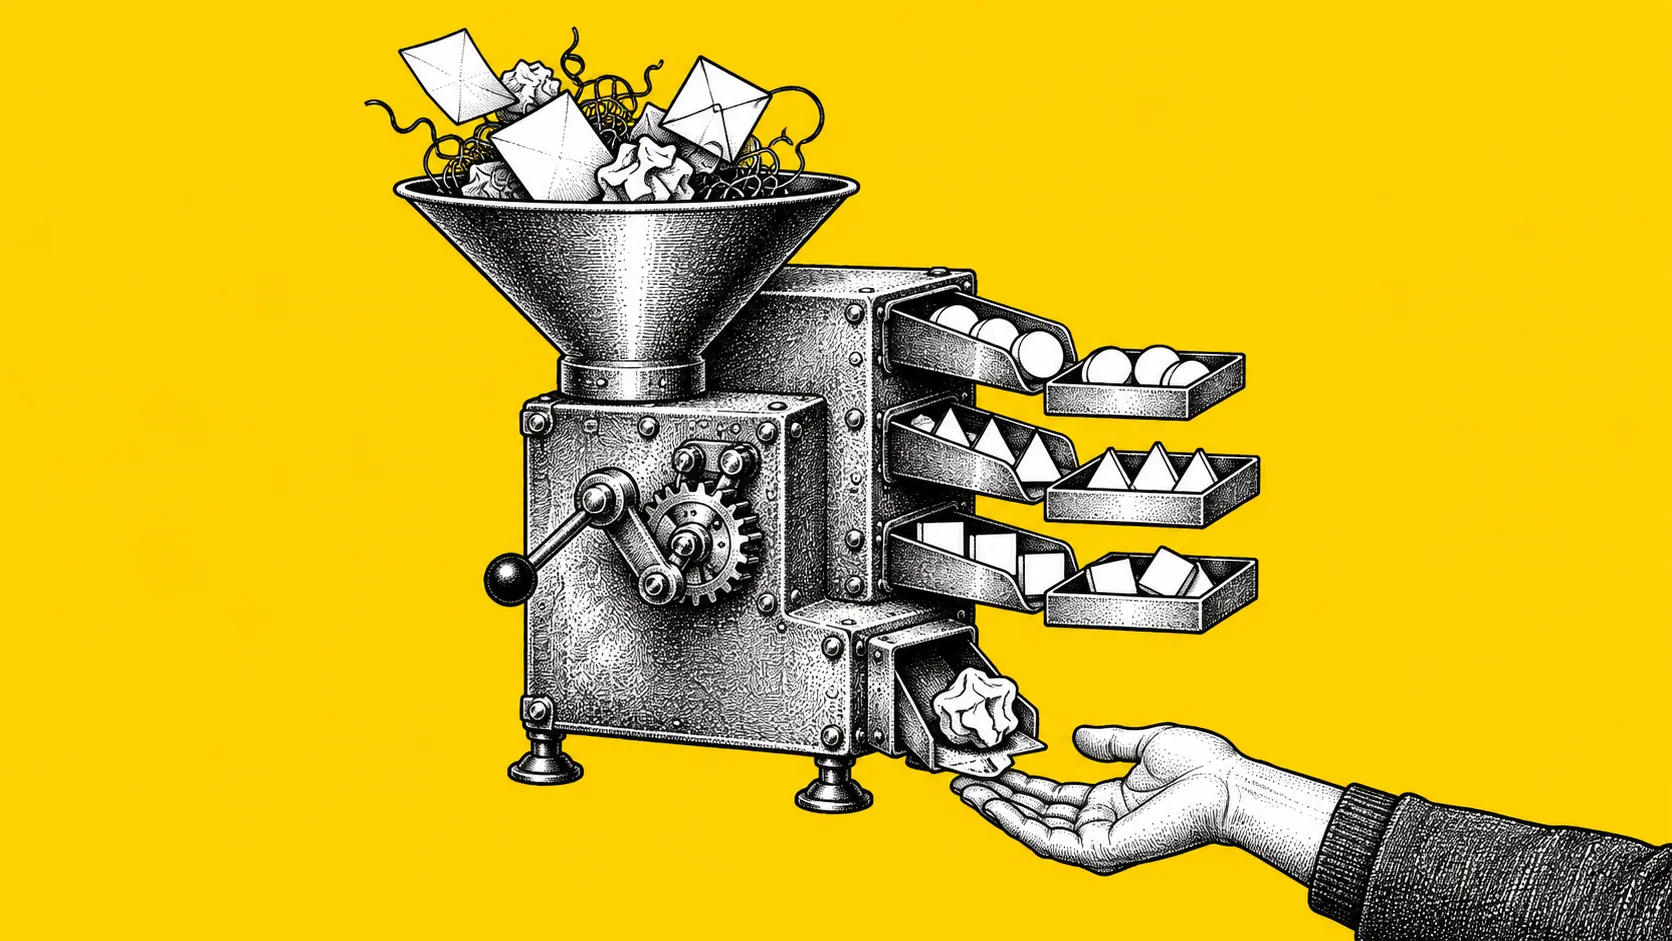
Anyone viewing Jev as a replacement for a general-purpose language model has missed the crucial point. TypeSafe AI positions the model as a machine-native decision function. Unstructured data goes in. A typed, probabilistic decision comes out.
That sounds less spectacular than a model that builds entire applications. For real-world automation, however, it might be more relevant. Many systems do not need eloquent text. They need to decide whether an email is important, which category a document belongs to, or whether a case must be escalated to a human.
TypeSafe AI refers to Jev as a System 1 model. The term draws on the distinction between fast, intuitive judgment and slow, deliberate thinking. Jev is built for the fast side. It reacts to a given state instead of developing a long chain of thought.
1. Classify
Emails, messages, videos, tickets, or logs can be assigned to fixed categories. This is particularly well suited for large volumes of data where a general-purpose language model would be too slow or too expensive.
2. Evaluate and prioritize
Jev can evaluate or rank data based on predefined options. This includes urgency, relevance, risk, and other clearly defined attributes.
3. Control processes
The model can decide between multiple paths like an intelligent if-statement. High confidence triggers an action. Uncertain cases are routed to a more capable model or to a human.
4. Check outputs
Moderation, safety filters, simple guardrails, and the detection of suspicious inputs fit the concept well. Complex domain-specific judgments, on the other hand, do not.
The most important technical difference lies in the output. Developers define in advance which structure and which values are permitted. Jev returns its decision within this schema. According to TypeSafe AI, this prevents invalid fields or malformed JSON structures.
Still, the term hallucination-free requires a clear boundary. Jev can make a decision that is formally valid and yet factually wrong. Zero formatting errors do not mean zero substantive errors. Anyone conflating these two things will build an unreliable system with astonishing efficiency.
Jev is also only partially deterministic. The structure of the output is fixed. The content remains a probabilistic decision. For that reason, the model provides probabilities and confidence scores so that software does not have to accept every response blindly.
That is practical. For example, a system can act automatically when confidence is high, call in a more powerful model when confidence is moderate, and ask a human when confidence is low. Each team will need to test specific threshold values using its own data. Independent, public evaluations regarding calibration are currently lacking.
The performance claims are remarkable. On its website, TypeSafe AI cites 193.6 times higher speed and 444.6 times lower costs for selected System 1 workflows. One comparison shown took 0.114 seconds with Jev and cost $0.000081. The compared workflow using general-purpose language models took 8.566 seconds and cost $0.013880.
The official pricing is listed at $42 per billion input tokens. Output tokens are not billed separately. That aligns with the architecture: Jev does not generate lengthy texts token by token, but rather returns typed decisions.
These figures, however, originate from the vendor and from selected demonstrations. Full datasets, test methodologies, and independently reproduced results are not comprehensively available. TypeSafe AI itself describes the particularly high gains as the upper bound of what should be expected in real-world applications.
The right question is therefore not whether Jev is categorically better than a language model. The question is how much thinking a task requires. If a human could answer almost instantly after reviewing all the information, Jev is likely a good fit. If analysis, planning, synthesis, or multi-step trade-offs are necessary, a different tool is needed.
Email sorting serves as a good example. In one showcased application, 100 emails were classified with an average of around 200 milliseconds per message. As a first tier for spam, prioritization, and broad categories, that is plausible. Determining whether a complex message is legally relevant or strategically important, by contrast, demands more context and judgment.
The gaming demos illustrate both sides as well. In checkers, Jev responded almost instantly to the game state passed to it. It did not play well. In a Doom demo, the model made decisions multiple times per second, but would alternate back and forth between left and right because each request was treated as a completely fresh state.
The model is therefore not an autonomous planner. It is a fast component within a larger system. The application itself must manage state, history, rules, and the consequences of those decisions.
Unsuitable: evaluating complex model responses
A fast classifier does not automatically have enough context to weigh multiple extensive solutions against each other. That requires domain understanding and often multi-step reasoning.
Unsuitable: compressing context
Context compression is not a simple selection of relevant lines. It must meaningfully summarize history, tool results, decisions, and dependencies. Jev is too superficial for this and lacks all the necessary information.
Unsuitable: generating code or text
Jev was not built for freeform string output. Anyone attempting to turn it into a code generator is working against the model instead of leveraging its strengths.
Unsuitable: replacing clear business rules
If a rule can be formulated completely and stably, standard code remains simpler, more transparent, and deterministic. AI is not mandatory.
The compelling use case sits between rigid rules and expensive reasoning models. Where natural language or confusing data overwhelms a traditional if-statement, but the decision is still rapid and tightly bounded, Jev can make sense.
That is precisely where teams should run tests. With real data, clear schemas, measured error rates, and a clean escalation path. High speed is worthless if a system confidently automates the wrong cases.
Treat Jev like an intelligent function
Jev is not a replacement for reasoning models. It is a fast, cost-effective, and strictly structured decision function for software. Use it to classify, sort, evaluate, and route. As soon as a task demands genuine deliberation, Jev is the wrong tool. That boundary does not make the model weak. It finally makes its practical application clear.