Tokens are the new currency: Comparing OpenAI, Anthropic, and Google
Why GPT-5.5 matches or outperforms Claude Sonnet 5 and Gemini using a tenth of the tokens
A quick framing before we look at the numbers. A model processes input tokens—everything you feed into it—and produces output tokens, meaning the response. With modern models, a third metric comes into play: reasoning tokens. These are the tokens a model requires to think to itself before it responds.
It is precisely these reasoning tokens that represent the number one cost factor. Each round of thinking is not only generated once; with every subsequent step, it loops back into the next prompt as history. A model that thinks at length and verbosely pays this price multiple times over. This is where the widest divide between providers emerges.
| Model | Tokens per task (Deep SWE) | Trend |
| GPT-5.5 Medium | approx. 20,000 | high score, very efficient |
| GPT-5.5 X High | approx. 46,000 | highest score in the series |
| Claude Opus 4.8 | approx. 50,000 | lower score than GPT-5.5 Medium |
| best Gemini model | approx. 270,000 | roughly half the score of OpenAI |
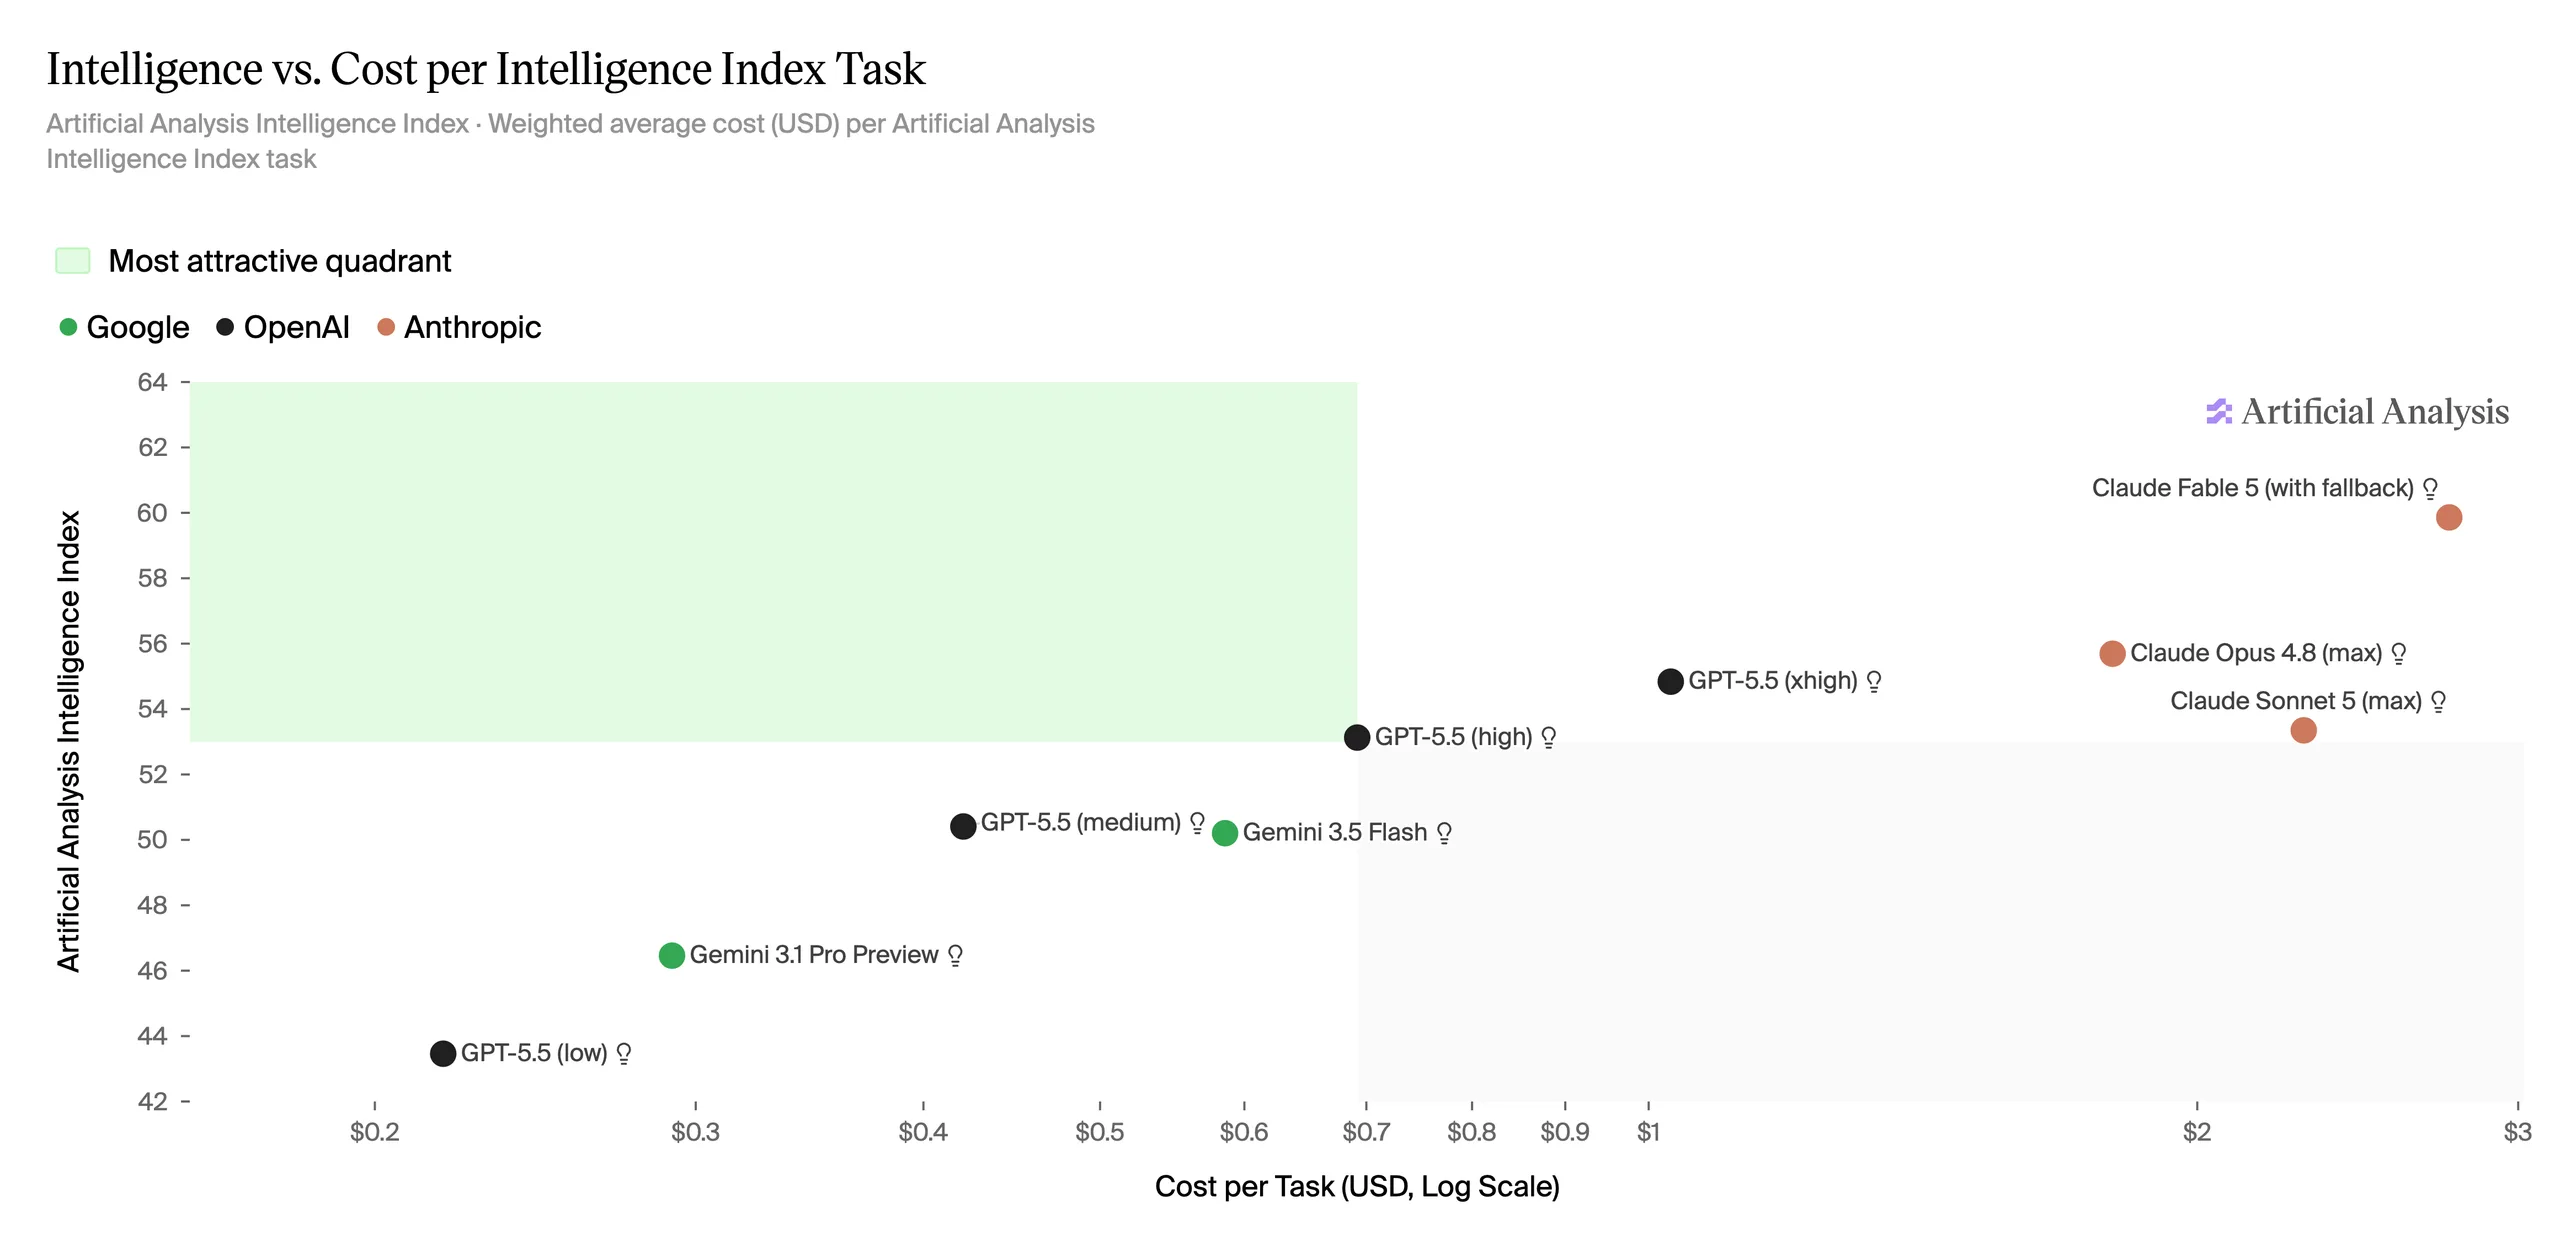
This is not a minor difference. Gemini requires twelve to fourteen times as many tokens as GPT-5.5 and ends up delivering about half the score. Anyone who only looks at the price per million tokens misses the real picture. Efficiency per resolved task is the metric that counts.
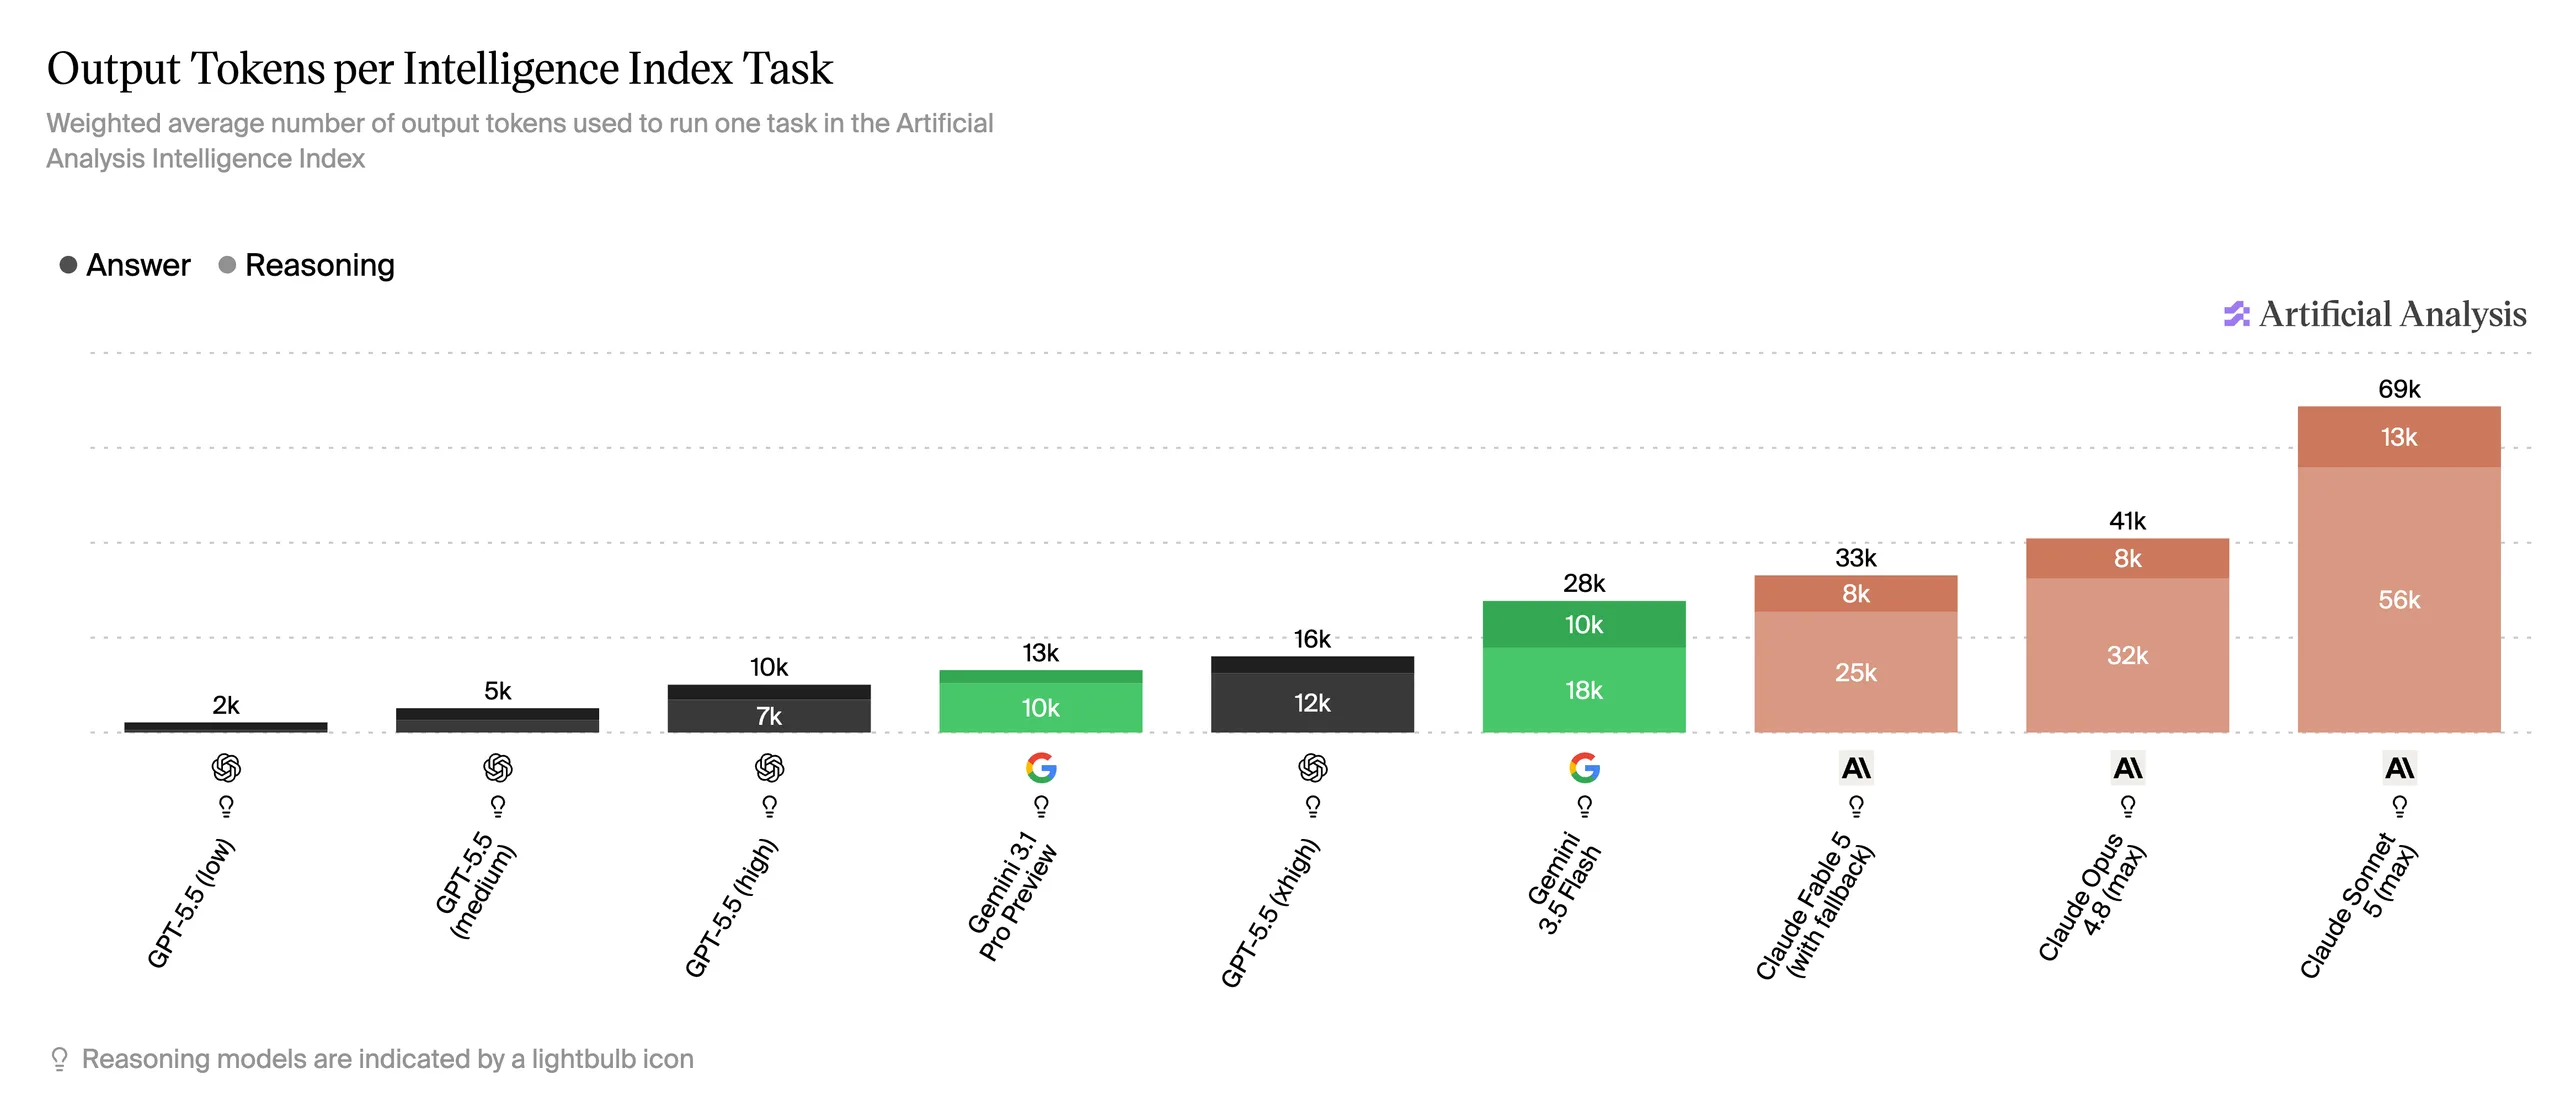
Claude Sonnet 5 illustrates the problem even more clearly. In practice, it consumed almost twice as many tokens as Opus 4.8 and, in some cases, nearly five times as many as GPT-5.5 at the highest reasoning tier. Where GPT-5.5 Medium required around 5,000 tokens for a task, Sonnet 5 reached 69,000. That is not an anomaly; it is a pattern.
On Cursor Bench, the same picture emerged from another angle. There, GPT-5.5 Medium achieved nearly the same score as Sonnet 5 at the Max tier, but at a significantly lower cost. Sonnet 5 High and Max were actually priced higher than the heaviest runs of GPT-5.5, despite weaker performance.
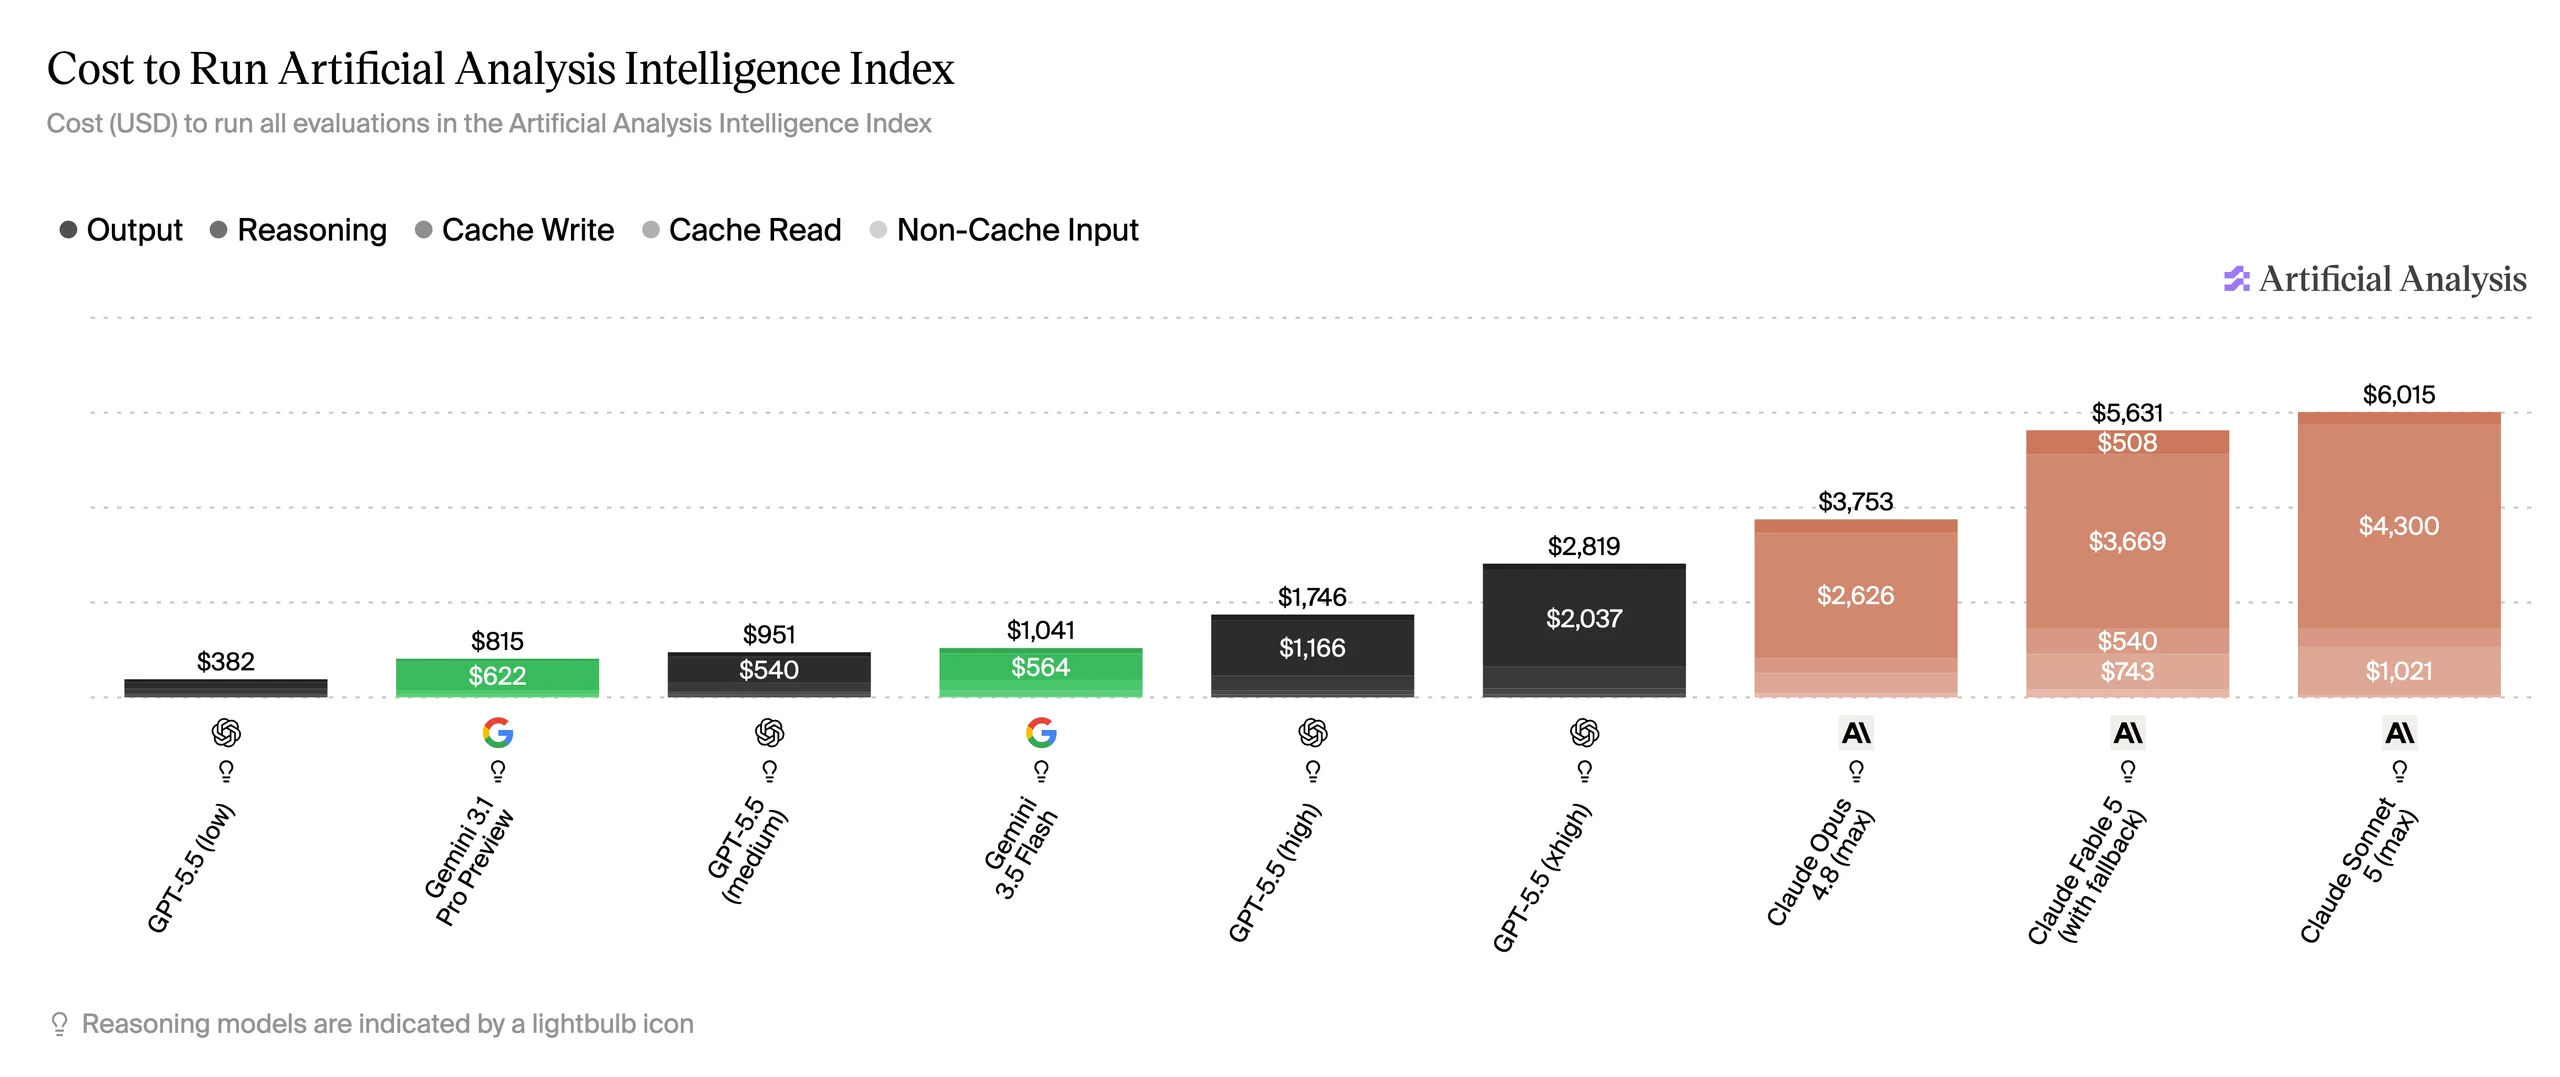
On a larger benchmark run by Artificial Analysis, Sonnet 5 became the most expensive model ever tested, with total costs of around $6,000, even surpassing Fable 5 at around $5,600. For the exact same run, GPT-5.5 Medium and Low cost only one-sixth and one-twelfth of that amount, respectively.
The question, then, is why OpenAI manages this so much better. A few reasons can be deduced from the models' behavior and from occasionally leaked reasoning traces.
1. Compact language of thought
Leaked reasoning traces from OpenAI models reveal an extremely condensed, almost telegraphic style, reminiscent of "Grok brain": sentences like "Try." instead of fully articulated considerations. Fewer words in the thinking process mean fewer tokens, and that multiplies across every subsequent step.
2. Hidden thinking stays hidden
No provider exposes the raw reasoning tokens; all provide only summaries. Anthropic used to release complete traces with Sonnet 3.5 and 3.6, but has discontinued this. Google showed no summaries at all for a long time. As a result, each provider's exact method remains a trade secret.
3. Incentive for efficiency
OpenAI optimized for efficiency early on because it makes models cheaper and faster to run at scale. Other providers whose revenue is directly tied to token consumption face less commercial pressure to radically shorten these thought processes.
4. Plain English costs more
Claude appears to think internally in elaborate, natural English, which makes the models pleasant to interact with, but also causes them to reason longer. This likely also explains why Claude requires larger context windows by default—not primarily because of larger codebases, but due to the length of its own reasoning logs.
It is also interesting to see how this impacts pricing. Compared to GPT-5.4, GPT-5.5 has practically doubled the price per million tokens, going from $2.50 to $5 for input and from $15 to $30 for output. Nevertheless, the effective cost per solved task decreases because GPT-5.5 Medium requires less than half as many tokens as GPT-5.4 at the highest tier, while performing even better.
The difference is also evident when looking at caching details. With GPT-5.5, one million uncached input tokens cost $5, while cached tokens cost only 50 cents. Anyone who designs their requests intelligently can drastically reduce input costs, whereas output costs remain the primary lever because that is where the expensive reasoning tokens are generated.
Open-source models like GLM-5.2 show by comparison how much headroom remains. GLM-5.2 required an average of around 42,790 tokens per task on Artificial Analysis, whereas GPT-5.5 Medium required only around 5,000 tokens for a similar intelligence level. That is one-tenth of the consumption.
Conclusion
Anyone who compares models solely by intelligence or price per million tokens is looking at the wrong numbers. What matters is how many tokens a model actually consumes to solve a task. By this yardstick, OpenAI is clearly in the lead, Google's Gemini is conspicuously inefficient, and Anthropic's Sonnet 5 is currently demonstrating quite impressively how a model can end up being the most expensive option despite a lower starting price.